
Modern smartphones do much more than run apps. They can recognize speech while you talk, remove background noise during calls, identify objects through the camera, translate conversations, enhance photos, and generate AI-assisted responses almost instantly.
Those features feel simple from the user’s point of view, but they require an enormous amount of computation.
That is where AI accelerators improve real-time features on mobile devices. Instead of forcing every machine-learning workload through the CPU or GPU, modern chipsets include specialized hardware designed to process neural-network operations much more efficiently.
These accelerators may appear as NPUs, neural engines, tensor processors, or AI-focused blocks inside larger system-on-chip designs.
Their biggest advantage is not simply higher AI benchmark scores. The real benefit is lower latency.
When a feature must react in milliseconds, every delay matters. Dedicated AI hardware can process incoming camera frames, audio signals, sensor data, and language inputs quickly enough to make the experience feel immediate.
That responsiveness is becoming one of the defining characteristics of modern mobile computing.
What AI Accelerators Actually Do
AI accelerators are specialized processors built to perform the mathematical operations common in machine learning.
Neural networks rely heavily on matrix multiplication, vector operations, tensor processing, and repeated multiply-accumulate calculations.
General-purpose CPUs can perform these tasks, but they are designed for a much wider range of instructions. AI accelerators devote more hardware to the calculations that neural models use most often.
Qualcomm’s Hexagon NPU is a good example. Qualcomm describes it as part of a heterogeneous AI architecture where the NPU works alongside the CPU and GPU to accelerate on-device inference efficiently.
Apple follows a similar strategy with its Neural Engine, while Arm provides neural-processing architectures for mobile and embedded systems.
The purpose is not to replace other processors.
It is to give AI workloads a faster and more efficient place to run when real-time response matters.
Real-Time Camera Features Depend on Fast AI Processing
Smartphone cameras are one of the clearest examples of AI acceleration in action.
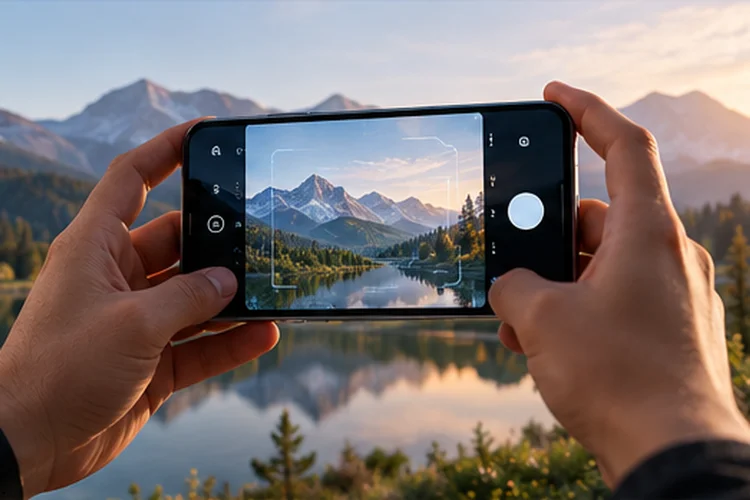
When you point a modern phone at a scene, the device may already be analyzing faces, depth, lighting, motion, objects, and exposure before you press the shutter button.
Those calculations happen continuously.
For portrait mode, the phone may identify the subject and separate it from the background. For night photography, AI can help align multiple frames and reduce noise. During video recording, it can track people or stabilize visual elements in real time.
These features are difficult to deliver smoothly if every frame must wait for slower general-purpose processing.
A 60 fps camera pipeline produces a new frame roughly every 16.7 milliseconds. That leaves very little time for image analysis before the next frame arrives.
Dedicated AI hardware helps process those models quickly enough to keep up.
Qualcomm specifically highlights AI-enhanced imaging and video as major workloads for its mobile AI Engine.
The faster the inference pipeline, the more sophisticated the camera feature can become without creating visible lag.
Voice Recognition Needs Extremely Low Latency
Speech is another workload where delay immediately affects usability.
Imagine using live transcription during a conversation.
If text appears two or three seconds after someone speaks, the experience feels disconnected. If the transcription appears almost instantly, it feels natural.
AI accelerators help reduce that gap.
Speech-recognition models analyze audio features continuously and convert them into text, commands, or semantic meaning.
The same hardware can also support voice assistants, wake-word detection, real-time captioning, and contextual language features.
Running these tasks locally has another advantage: the phone does not always need to send audio to a cloud server.
That eliminates the network round trip.
Qualcomm notes that on-device AI can reduce latency because inference happens locally rather than depending on a remote data center.
This becomes especially important when connectivity is weak or inconsistent.
Low-latency AI allows voice interfaces to feel like part of the device rather than a remote service.
Noise Reduction and Call Enhancement Run Continuously
AI does not only process obvious features like cameras and assistants.
It also works quietly in the background.
Modern phones can use neural networks to remove background noise, isolate voices, reduce wind interference, and improve call clarity.
These tasks need to happen continuously while the call is active.
That creates an interesting challenge.
The model must run quickly, but it must also use very little power because a phone call may last for an hour or more.
This is where specialized acceleration becomes especially valuable.
An NPU can often handle neural audio processing more efficiently than keeping high-performance CPU cores active continuously.
The result is better audio quality with lower battery consumption.
This type of workload explains why raw AI speed is not enough.
Real-time mobile AI must be fast and efficient enough to remain active for extended periods.
Translation Becomes More Natural With Local AI
Live translation is another feature that benefits directly from AI acceleration.
A real-time translation system may involve several separate stages.
First, the phone must recognize speech. Then it needs to interpret language, translate the meaning, and possibly generate synthesized speech in another language.
If every step adds delay, conversation becomes awkward.
Fast on-device inference can significantly reduce that latency.
Google has increasingly emphasized on-device AI through technologies such as Gemini Nano and AICore, which allow supported Android devices to run certain AI workloads locally.
Local processing can also improve reliability.
A translation tool that depends entirely on the cloud may become unusable in airports, airplanes, rural areas, or other places with weak connectivity.
AI accelerators make offline or partially offline translation much more practical.
That turns AI from a nice extra into something users can actually depend on in real-world situations.
AR and Computer Vision Need Frame-by-Frame Inference
Augmented reality is especially demanding because everything happens live.
A mobile AR app may need to understand walls, floors, objects, faces, motion, depth, and lighting while simultaneously rendering graphics.
This creates a constant stream of sensor data.
AI models may help identify objects, estimate pose, segment scenes, or understand spatial relationships.
The phone cannot pause for half a second every time it needs to recognize something.
Inference needs to happen frame by frame.
A dedicated accelerator can process computer-vision models while the GPU handles rendering and the CPU manages application logic.
This is a good example of heterogeneous computing.
Instead of one processor doing everything, the workload is divided among specialized engines.
Qualcomm’s AI Engine is explicitly designed around this approach, combining NPU, CPU, GPU, and sensor-processing capabilities.
The result is smoother AR, faster visual recognition, and lower power usage.
AI Accelerators Improve Power Efficiency Too
Real-time features can be expensive.
A camera, microphone, GPS receiver, display, and neural network may all be active at the same time.
If the phone used high-performance CPU cores for every AI task, battery life would suffer quickly.
Specialized accelerators improve performance per watt.
Because the hardware is designed specifically for neural-network operations, it can perform many AI calculations using fewer resources.
Arm emphasizes this principle in its neural-processing architecture, where dedicated AI hardware is designed to deliver efficient inference under strict mobile power limits.
This matters because sustained features are often more demanding than short benchmark tests.
A camera app may process AI continuously for several minutes. A call-enhancement model may run for hours.
Efficient acceleration keeps those features practical without turning the phone into a hand warmer.
Memory Bandwidth Can Become the Next Bottleneck
AI accelerators need data quickly.
A powerful NPU may be able to perform huge numbers of calculations every second, but it still depends on memory to provide model parameters and input data.
Real-time workloads make this especially challenging.
Camera frames, audio streams, language tokens, and sensor inputs arrive continuously.
If the memory subsystem cannot keep up, the accelerator spends time waiting instead of computing.
That is why modern chipsets increasingly combine faster memory, larger caches, and smarter data movement with stronger AI processors.
Qualcomm’s newer Hexagon designs have focused on expanding shared memory close to the NPU, reducing the need to access slower external memory as often.
This shows that AI performance is becoming a system-level challenge.
TOPS numbers alone do not tell you whether a phone can sustain responsive real-time inference.
Memory bandwidth, cache design, software optimization, and model size all matter.
Generative AI Is Expanding the Definition of Real-Time
Traditional mobile AI often dealt with compact models.
Generative AI introduces much heavier workloads.
A smartphone may now summarize text, rewrite messages, generate images, analyze screenshots, or respond conversationally.
Users still expect these features to react quickly.
That puts even more pressure on mobile AI hardware.
Google’s Gemini Nano is specifically designed for supported on-device generative AI experiences, allowing some tasks to run locally through Android’s AICore system.
Apple is taking a similar direction through Apple Intelligence, combining on-device models with cloud processing for tasks that need more computational capacity.
This hybrid model is likely to become common.
Short, latency-sensitive tasks can run locally. Larger or more complex requests can move to the cloud.
AI accelerators are what make the local side fast enough to feel interactive.
Not Every AI Feature Should Run on the NPU
Dedicated acceleration is powerful, but it is not always the best choice.
Some workloads may be too small to justify moving data to the NPU. Others may be better suited to the GPU because they already involve graphics processing.
There are also models whose operators are not fully supported by the accelerator.
In those cases, parts of the workload may fall back to the CPU or GPU.
This is why modern AI runtimes try to choose the most appropriate processor automatically.
The real goal is efficient workload placement.
A mobile chipset does not need every AI task to run on the NPU. It needs each part of the task to run where it makes the most sense.
That flexibility is what allows modern phones to combine performance, battery life, and thermal control.
Software Optimization Still Matters
Powerful hardware cannot fix inefficient software.
An AI model that is unnecessarily large, badly quantized, or poorly optimized may still run slowly.
Developers increasingly use techniques such as quantization, pruning, model distillation, and operator fusion to reduce computational cost.
Android provides hardware-accelerated machine-learning support through frameworks and runtimes that can target available device processors.
Apple similarly provides Core ML for optimizing and running machine-learning models across available Apple hardware.
These software layers are important because mobile AI hardware varies significantly between devices.
A good runtime can adapt to the available CPU, GPU, NPU, and memory configuration.
Real-time performance therefore depends on software and hardware working together.
AI accelerators are becoming essential to the real-time experience on modern mobile devices.
They help cameras recognize scenes instantly, allow speech systems to respond with lower latency, improve call audio, support translation, enable augmented reality, and make generative AI feel more interactive.
Just as importantly, they perform these tasks more effeciently than relying entirely on general-purpose processors. But accelerator speed alone does not determine performance.
Memory bandwidth, model optimization, software runtimes, thermal limits, and cooperation between the CPU, GPU, and NPU all influence how responsive a feature feels.
When evaluating future smartphones, look beyond headline AI TOPS.
Pay attention to what the device can actually do in real time, how long it can sustain those features, and whether they still work smoothly without constant cloud access. That is where AI acceleration becomes genuinely useful.
