
Artificial intelligence on smartphones used to depend heavily on the cloud. Your phone captured some data, sent it to a remote server, waited for powerful computers to process it, and then downloaded the result.
That model is changing quickly.
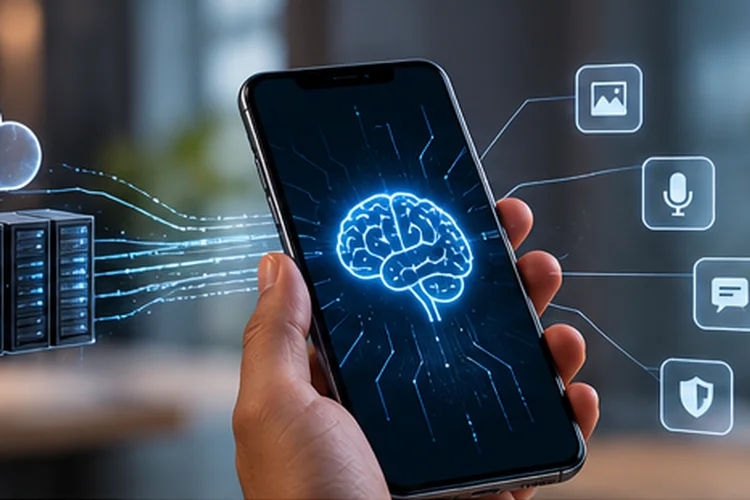
Modern smartphones increasingly run machine-learning and generative AI models directly on the device.
Dedicated neural processing units, faster memory, optimized models, and more capable mobile chipsets can now handle tasks ranging from photo enhancement and speech recognition to summarization and generative AI.
Understanding how on-device AI changes privacy and performance on smartphones is becoming important because this shift changes more than processing speed.
It affects where personal information travels, whether features work offline, how quickly AI responds, and how much battery and memory the device consumes.
Local AI is not replacing cloud computing completely. Instead, the industry is moving toward a hybrid model where smartphones process appropriate workloads locally while larger or more complex tasks can still use cloud infrastructure.
The balance between those approaches will increasingly shape the smartphone experience.
What On-Device AI Actually Means
On-device AI means an artificial intelligence model performs inference directly on the smartphone instead of sending every request to a remote data center.
Inference is what happens when an already-trained model receives new information and produces an output.
For example, an AI model could analyze an image to identify an object, summarize text, remove background noise during a call, or generate a suggested reply.
Google’s Gemini Nano provides a modern example. Android’s AICore system service can run Gemini Nano locally using hardware accelerators, allowing supported applications to perform generative AI tasks without requiring a network connection or sending the prompt to the cloud.
Traditional AI features have already used this approach for years. Computational photography, face detection, predictive typing, and voice processing frequently perform at least part of their work locally.
What is changing is the scale.
Smartphones are now beginning to run much larger foundation models capable of more flexible language, image, and multimodal tasks.
Local Processing Can Improve Privacy
Privacy is one of the strongest arguments for on-device AI.
When information is processed locally, the original data may not need to leave the smartphone.
That matters when AI features interact with sensitive information such as private messages, photographs, phone conversations, documents, or personal activity.
Google states that ML Kit processing happens on-device and that input data and resulting outputs are not sent to Google servers by those APIs.
Gemini Nano follows a similar philosophy for supported Android features. Google says local generative AI eliminates server calls and keeps sensitive information on the device.
Apple also makes on-device processing a central part of Apple Intelligence. The company says many requests can be handled locally, allowing its intelligence features to use personal context without routinely collecting that information in the cloud.
This does not automatically make every AI feature private. Applications still need good permission controls, secure storage, and responsible software design.
But reducing unnecessary data transfers removes one important point of exposure.
On-Device AI Can Reduce Latency
Privacy is only part of the benefit.
Local AI can also respond faster because the phone does not always need to communicate with a distant server.
Cloud AI introduces network latency.
A request must travel from the smartphone to a server, enter a processing queue, run inference, and send a response back. Even when cloud processing itself is extremely fast, unreliable connectivity can add noticeable delays.
On-device inference removes that round trip.
Android says Gemini Nano through AICore uses device hardware to provide low inference latency.
This advantage becomes particularly useful for interactive features.
Real-time transcription, keyboard suggestions, photo processing, accessibility tools, voice interfaces, and camera-based AI can feel substantially better when responses arrive immediately.
Qualcomm similarly argues that local generative AI can reduce latency because information no longer needs to constantly travel between the device and cloud servers.
For users, that translates into AI features that feel more like part of the operating system rather than a remote web service.
AI Features Can Work Without an Internet Connection
Another major advantage is offline functionality.
Cloud-based AI becomes unavailable when the network disappears.
That may not matter while sitting at home on fast Wi-Fi, but mobile devices regularly encounter poor connections. Users travel through tunnels, airplanes, elevators, rural areas, and crowded networks.
Local models continue working because the required computation already exists on the phone.
Gemini Nano, for example, supports AI experiences without needing an active network connection for the inference itself.
This can make features such as summarization, text processing, image understanding, and certain assistance tools significantly more reliable.
Offline capability is especially useful for travel and accessibility applications.
A translation or transcription feature becomes far more valuable when it continues functioning precisely when the user cannot access a reliable network.
NPUs Make Local AI Practical
Running AI locally would be difficult if smartphones relied only on conventional CPU cores.
Modern mobile chipsets therefore include dedicated neural processing units, usually called NPUs.
An NPU is optimized for the mathematical operations commonly used by neural networks.
The CPU remains useful for sequential logic, while GPUs excel at massively parallel graphics and computing workloads. NPUs specialize further in tensor, vector, and other AI-related calculations.
Qualcomm describes modern mobile AI as a heterogeneous computing problem where CPU, GPU, NPU, and other processors cooperate depending on the workload. This approach can improve performance while managing thermal output and battery life.
The difference matters because smartphones operate under extremely strict power limits.
A desktop computer can use large cooling systems and consume hundreds of watts. A phone must fit powerful AI processing into a thin device powered by a small battery.
Specialized hardware makes that possible far more effeciently than forcing general CPU cores to perform every calculation.
Local AI Still Uses Battery Power
On-device processing does not mean free processing.
AI inference consumes energy.
Large models may keep the NPU, memory subsystem, CPU, or GPU active for extended periods. That activity generates heat and drains the battery.
This creates an interesting trade-off.
Cloud processing shifts most computation away from the smartphone but requires wireless communication. Local inference eliminates much of that communication but moves computational work back onto the device.
Which method is more efficient depends on the model, hardware, connectivity, and workload.
Qualcomm has highlighted research suggesting that some local AI workloads can consume substantially less overall inference energy than equivalent cloud-based processing, although results depend heavily on testing conditions and infrastructure.
Smartphone designers therefore focus heavily on performance per watt.
Efficient NPUs, quantized models, optimized memory access, and intelligent task routing allow phones to perform increasingly sophisticated AI without destroying battery life.
Memory Is Becoming a Major AI Bottleneck
AI models do not only need computing power.
They need memory.
Model parameters have to be stored somewhere, loaded into RAM, and moved efficiently through the processor during inference.
Larger models therefore increase pressure on both storage capacity and memory bandwidth.
This is one reason local smartphone models are usually smaller than the enormous models running inside data centers.
Developers use techniques such as quantization to reduce model size. Instead of representing model values with high-precision formats everywhere, optimized models can use lower-precision formats that consume less memory and computational power.
Newer mobile AI architectures are also improving caching and shared memory.
Qualcomm’s latest Hexagon NPU architecture, for example, emphasizes larger shared memory and support for lower-precision AI calculations to reduce memory traffic while keeping AI agents responsive.
These optimizations are becoming just as important as raw AI processing speed.
A powerful NPU cannot perform at its best if it is constantly waiting for model data.
On-Device AI Enables Deeper Personalization
Local processing creates another interesting opportunity: personal AI that can use device context without constantly uploading it.
A smartphone already contains enormous amounts of context.
There may be messages, calendars, photos, notifications, app activity, contacts, location history, and personal preferences.
Processing some of that information locally can enable highly personalized features while reducing how much sensitive context needs to leave the device.
Google has demonstrated this idea with Gemini Nano-powered features such as Call Notes and Pixel Screenshots, where sensitive information can be processed locally for supported use cases.
Apple uses a similar approach with Apple Intelligence, combining local models with personal context on supported devices.
Personalization could therefore become one of the biggest reasons local AI matters.
The smartphone is uniquely positioned to understand its owner because it already contains so much relevant context.
The challenge is doing that without turning personalization into surveillance.
Local AI Does Not Eliminate the Cloud
There are still major limitations to running everything locally.
Smartphones have finite RAM, storage, battery capacity, and thermal headroom.
Cloud data centers can run models containing far more parameters using powerful GPUs and enormous memory systems. They can also access constantly updated information and perform compute-intensive reasoning that would be impractical on a phone.
This is why hybrid AI is likely to dominate.
Simple, privacy-sensitive, or latency-critical workloads can run locally. More complicated tasks can move to larger cloud models when necessary.
Apple Intelligence follows exactly this principle. Apple says tasks are analyzed to determine whether they can be processed on-device, while workloads requiring greater computational capacity can use Private Cloud Compute.
Qualcomm likewise describes hybrid AI as an architecture that coordinates workloads between devices and cloud infrastructure.
The question is increasingly not “device or cloud?”
It is “which processor is best for this particular task?”
Thermal Management Will Limit Sustained AI Performance
AI workloads can also heat smartphones.
Generate a short text summary and the workload may finish quickly enough that temperature barely matters. Run continuous multimodal processing, image generation, or an AI agent for several minutes and thermal limits become more important.
Once a phone becomes too warm, its processor may reduce frequencies to control temperature.
That means sustained AI performance depends on cooling design as well as NPU specifications.
Efficient models help here too.
If an optimized model completes the same task using fewer memory transfers and less computation, it produces less thermal pressure.
Qualcomm specifically connects heterogeneous processing with improved thermal efficiency because workloads can be directed toward hardware that handles them most effectively.
As smartphones become more AI-centric, thermal efficiency may become one of the hidden differences between devices that look similar on paper.
Privacy Still Depends on the Entire System
There is one important caveat: “on-device” should not automatically be interpreted as “completely private.”
An app could process AI locally and still collect unrelated analytics data.
Models may also require downloads or updates, and some features may switch between local and cloud processing depending on the task.
Users therefore need transparency about where processing occurs.
Google’s AICore architecture is designed to isolate local AI requests and does not retain processed input or output after the request, according to Android documentation.
Apple similarly provides reporting capabilities that can show when Apple Intelligence requests have used Private Cloud Compute rather than remaining entirely local.
These mechanisms matter because AI features increasingly interact with highly personal information.
Privacy depends not only on where computation happens, but also on what data is collected, how long it is stored, and who can access it.
On-device AI is changing smartphones by moving more intelligence from distant servers directly into users’ pockets.
Local processing can improve privacy, reduce network latency, enable offline features, and create deeper personalization. Dedicated NPUs and optimized models make increasingly sophisticated AI possible within mobile battery and thermal limits.
However, local processing also introduces challenges involving memory, storage, battery consumption, and sustained performance. Large or computationally intensive models will still need cloud infrastructure.
That is why the future will probably be hybrid rather than purely local.
When comparing future smartphones, look beyond headline AI features. Pay attention to the NPU, memory capacity, efficiency, privacy architecture, and which features genuinely run on-device.
The smartest phone may ultimately be the one that knows when not to send your data somewhere else.
